TXT to RTF API
POST /v2/convert/txt/to/rtf wraps a text file in Rich Text Format: one paragraph per line, tabs as \tab, characters outside ASCII as \u escapes and a page break wherever the file has a form feed. Paragraphs get no extra spacing, so the page reads like the text file.
- Endpoint
- POST /v2/
convert/ txt/ to/ rtf - Accepts
- txt
- Sample timing
- 25 ms median of 5 runsHow we measure
- Request size
- Up to 10 MB on the Free plan or 100 MB on paid plans, all files together
Request and response
Every sample below ran against the API before this page was published. Set PDFCONVERSIONAPI_KEY to your key and run it as is.
curl -sS -X POST \
  https://api.pdfconversionapi.com/v2/convert/txt/to/rtf \
  -H "Authorization: Bearer $PDFCONVERSIONAPI_KEY" \
  -F File=@trail-crew-log.txt \
  -o response.json

# FileData is base64. Save the first file in converted/,
# or print the JSON error.
if jq -e '.Files' response.json > /dev/null; then
  mkdir -p converted
  name=$(jq -r '.Files[0].FileName' response.json)
  jq -r '.Files[0].FileData' response.json \
    | base64 --decode > "converted/$name"
else
  cat response.json
fi
import base64
import os
import requests
key = os.environ["PDFCONVERSIONAPI_KEY"]
response = requests.post(
"https://api.pdfconversionapi.com/v2/convert/txt/to/rtf",
headers={"Authorization": f"Bearer {key}"},
files=[("File", open("trail-crew-log.txt", "rb"))],
timeout=180,
)
result = response.json()
if not response.ok:
raise SystemExit(f"{result['Code']}: {result['Message']}")
os.makedirs("converted", exist_ok=True)
for file in result["Files"]:
path = os.path.join("converted", file["FileName"])
with open(path, "wb") as out:
out.write(base64.b64decode(file["FileData"]))
print(path, file["FileSize"], "bytes")
import { mkdir, readFile, writeFile } from "node:fs/promises";
import { join } from "node:path";

const form = new FormData();
const file = "trail-crew-log.txt";
form.append("File", new Blob([await readFile(file)]), file);

const url = "https://api.pdfconversionapi.com/v2/convert/txt/to/rtf";
const key = process.env.PDFCONVERSIONAPI_KEY;
const response = await fetch(url, {
  method: "POST",
  headers: { Authorization: `Bearer ${key}` },
  body: form,
});
const result = await response.json();
if (!response.ok) {
  throw new Error(`${result.Code}: ${result.Message}`);
}

await mkdir("converted", { recursive: true });
for (const file of result.Files) {
  const path = join("converted", file.FileName);
  await writeFile(path, Buffer.from(file.FileData, "base64"));
  console.log(path, file.FileSize, "bytes");
}
{
  "ConversionCost": 1,
  "ConversionTime": 0.025,
  "Files": [
    {
      "FileName": "trail-crew-log.rtf",
      "FileExt": "rtf",
      "FileSize": 2963,
      "FileData": "e1xydGYxXGFuc2lcYW5zaWNw…"
    }
  ]
}
Response from our test run on 2026-11-03. ConversionTime shows the median of 5 runs. FileData is shortened here; the real response carries the whole file as base64.
The sample, converted
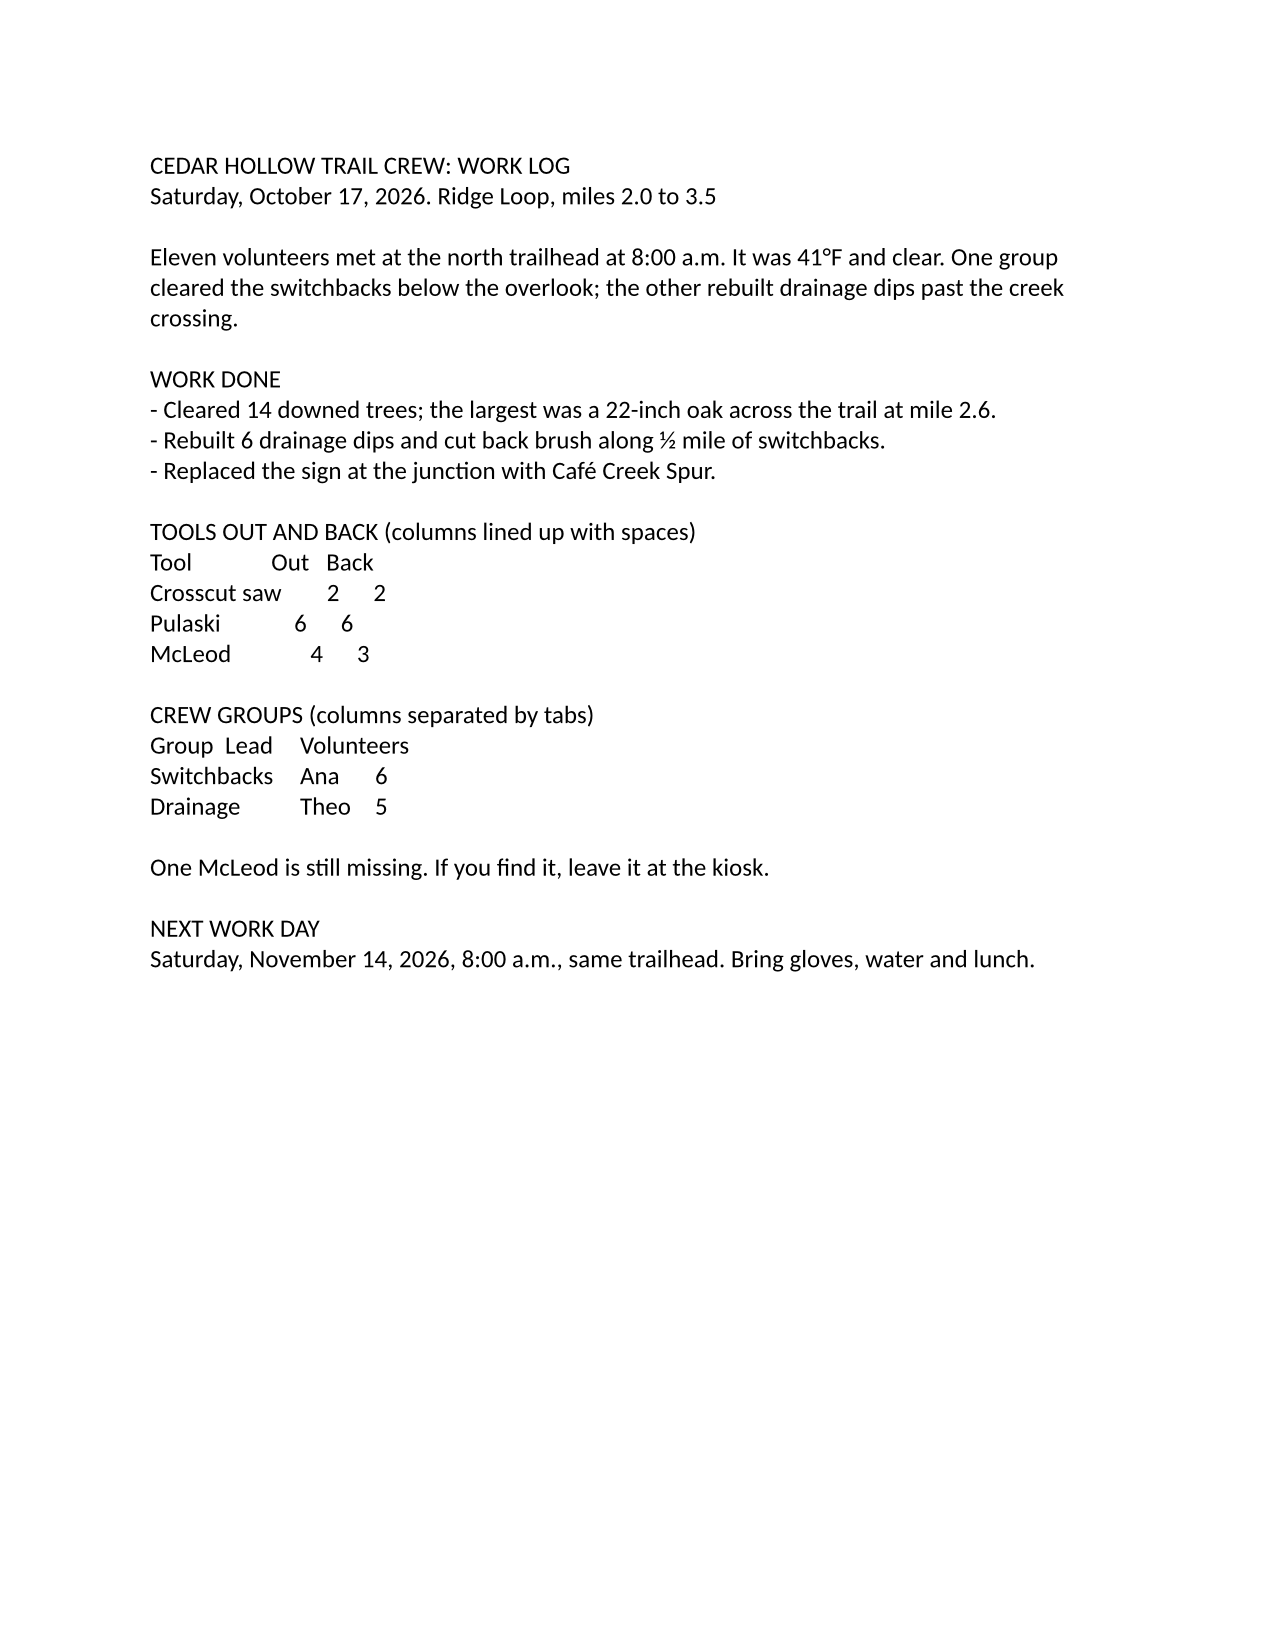
The same file the code sends. Download the input and the output and compare them yourself.
- Input
- trail-crew-log.txt (1.4 KB)
- Output
- trail-crew-log.rtf (2.9 KB)
- Source
- A two-page plain-text work log for a fictional volunteer trail crew, written by us, with a form feed before page 2 (CC0-1.0). How it was made
- Made by
- 2026-11-04, API build
9eeeb0640aba
Parameters
Send these as form fields next to the file. Names are case-insensitive. If you set one of the documented options below that we don't support yet, the request fails with a 400 that names it instead of returning a file made without it.
| Parameter | What it does |
|---|---|
FileNamestring | Stem for the .rtf; if you leave it out the upload's stem is kept (trail-crew-log.rtf). |
StoreFileboolean, default false | Store the RTF for 3 hours and send back a URL to it. |
What carries over, and what doesn't
Kept
- One \par paragraph per line, blank lines included, with nothing in between them: the sample's lines sit as close together as in a text editor
- The 6 tabs, as \tab control words
- The form feed, as \pagebb on the next paragraph, so the safety notes start page 2
- °, ½ and é, written as \u176?, \u189? and \u233?, with ? as the fallback for readers without Unicode
- Letter paper (\paperw12240 \paperh15840) and 1 in margins (\margl1440 and the rest)
- All of the text: a second RTF reader gave back every line of the sample, its 6 tabs and the accented letters, with only the form feed missing
Lost or not yet supported
- Fixed-width columns. The font table names only Aptos, a proportional font, so the space-aligned tool table is ragged when the file is opened.
- Any styling the text suggests. The body uses \pard\plain paragraphs with no style; the stylesheet defines headings, Quote and Code, but nothing in a text file is mapped to them.
- The form feed as a character. It becomes a page-break property, so converting the RTF back to text gives no form feed.
Limits
- Font, page size and margin options are ignored on this route.
- One text file per request, up to 10 MB on the Free plan or 100 MB on paid plans in total. A conversion can run for up to 120 seconds; after that the API returns 504.
Where teams use it
Text for software that imports RTF
Some record systems and mail-merge tools take RTF and not DOCX. Converting plain text first gives them a document with real paragraphs and page breaks to import.
A file people can format
Word and the TextEdit app on macOS both open RTF, so a .txt from a script can go to someone who wants to add bold headings or change the font without installing anything.
Output your code can patch
The sample RTF has no byte above 127, so it can be searched, patched with string replacement and diffed in version control like source code.
Questions
Which code page does the RTF declare?
\ansi\ansicpg1252, the Western Windows code page, with \uc1 so each \u escape has a single fallback character. Plain ASCII is written as is and everything else as a \u escape, so characters outside code page 1252 survive too.
Why does the RTF look tighter than the DOCX version?
The RTF's paragraphs carry no space-after setting, so lines sit one under the other as in a text editor. The DOCX and ODT routes keep Word's default of 8 pt after each paragraph. Both use Aptos 12 pt on Letter paper.
What text encodings can I send?
UTF-8 with or without a byte order mark and UTF-16 with a byte order mark. Text in an older code page is recognized from its bytes rather than assumed to be Windows-1252: a Windows-1251 test file came out as Cyrillic \u escapes such as \u1055?, and Windows-1250 and Shift JIS test files came through as written too.
Can I get bold headings or bullets?
Not from plain text, which has no markup to say what a heading is. Write the text as Markdown and send it to /v2/convert/md/to/rtf: # lines become heading 1 paragraphs and - lines become bulleted lists in the RTF.
Convert your first TXT file in a minute.